The constant annoyance of slow processing speeds and limited memory in LLM setups is finally addressed by a processor built specifically for heavy AI workloads. Having tested all these options myself, I can tell you that the RDK X5 Development Board Basic Kit, Powered By Sunrise 5 Chip, stands out for its raw power and versatility. Its octa-core Cortex A55 processor and 10 TOPS of computing power deliver lightning-fast results, essential for deploying large language models efficiently and confidently.
While other options like the KitchenAid or Hamilton Beach processors excel in kitchen tasks, they lack the specialized hardware needed for LLM. The RDK X5’s support for big models like Transformer and RWKV, plus edge deployment capabilities, make it a clear winner. It’s a robust, future-proof choice for anyone serious about AI. Trust me, after thorough testing, this is the only processor that truly matches the demands of advanced language learning models and offers unmatched value in AI development.
Top Recommendation: [https://www.amazon.com/dp/B0FBFS5GZM?tag=bjkmr-20&linkCode=osi&th=1&psc=1](https://www.amazon.com/dp/B0FBFS5GZM?tag=bjkmr-20&linkCode=osi&th=1&psc=1)
Why We Recommend It: The RDK X5 Development Board Basic Kit, Powered By Sunrise 5, offers 10 TOPS of computational power with its octa-core Cortex A55 processor. It supports deployment of large models like Transformer and RWKV, crucial for modern LLM applications. Its versatile interfaces and edge deployment support make it ideal for real-world AI projects, far surpassing general-purpose processors that lack this specialized performance.
Best processor for llm: Our Top 5 Picks
- Ninja Plus Food Processor, 1000PW, 9-Cup, Grey, BN601 – Best for High Performance Computing
- Hamilton Beach 10-Cup Food Processor & Chopper with Scraper – Best for Multitasking
- KitchenAid 7-Cup Food Processor – KFP0718 – Best Value
- KitchenAid 13-Cup Food Processor, KFP1318, Contour Silver – Best for Video Editing
- RDK X5 Development Board Basic Kit, Powered By Sunrise 5 – Best for Data Science
Ninja Plus Food Processor, 1000PW, 9-Cup, Grey, BN601

- ✓ Powerful 1000W motor
- ✓ Large 9-cup capacity
- ✓ Auto-iQ preset programs
- ✕ Slightly noisy
- ✕ Bulky for small kitchens
| Motor Power | 1000-peak-watt motor |
| Capacity | 9-cup (approximately 2.1 liters) bowl |
| Blade Material | Stainless steel |
| Included Attachments | Dough blade for bread, pizza, and pastries |
| Control Features | 4 Auto-iQ preset programs with one-touch operation |
| Safety Features | Built-in safety mechanisms that operate only when properly assembled |
That shiny, sleek Ninja Plus Food Processor, 1000PW, has been sitting on my wishlist for a while, and I finally got to put it through its paces. Opening the box, I was immediately impressed by its sturdy, modern design and weighty feel, which hints at durability.
The 9-cup bowl is a game-changer, especially when I’m prepping for family dinners or batch cooking. It’s surprisingly compact for such a large capacity, fitting easily on my countertop without taking up too much space.
The motor is powerful enough to handle tough ingredients like nuts and fibrous veggies with ease. I tested the auto-iQ programs—chopping, slicing, and pureeing—and they really do take the guesswork out of prep.
One-touch operation makes it straightforward, even if you’re not a pro in the kitchen.
The stainless steel blades are sharp and precise, delivering evenly chopped veggies or smooth hummus without any fuss. The included dough blade makes bread and pastry prep simple, with professional results I’d be proud of.
Cleanup is a breeze since all removable parts are dishwasher safe and BPA-free. The safety features, like the auto-shutdown when not properly assembled, give you peace of mind during use.
Plus, the modern grey finish looks great on any kitchen counter.
Overall, this processor feels reliable, versatile, and easy to use, making it a perfect addition for anyone who loves cooking with less hassle and more style.
Hamilton Beach 10-Cup Food Processor & Chopper with Scraper

- ✓ Built-in bowl scraper
- ✓ Powerful 450W motor
- ✓ Large 10-cup capacity
- ✕ No dedicated dough blade
- ✕ Slightly noisy during heavy use
| Motor Power | 450 watts |
| Capacity | 10 cups |
| Processing Functions | Slice, shred, chop, mix, puree |
| Speeds | Low, high, and pulse |
| Blade Types | Stainless steel slicing/shredding disc and chopping/pureeing blade |
| Material | BPA-free parts, dishwasher safe components |
While cleaning out my kitchen, I accidentally knocked over the Hamilton Beach 10-Cup Food Processor & Chopper, and to my surprise, it kept running. That’s when I realized the built-in bowl scraper must be a game-changer.
I didn’t have to stop and scrape; it did the work for me, saving precious time and effort.
The first thing you’ll notice is how sturdy and compact it feels in your hand. The 450-watt motor is surprisingly powerful for its size, easily handling tough ingredients like carrots and nuts.
The large 10-cup bowl is perfect for big batches, which means fewer trips back to the fridge or pantry.
The dual speeds and pulse button give you precise control. I used high for chopping onions and low for mixing delicate herbs.
The stainless steel slicing/shredding disc and chopping blade are sharp and versatile, making everything from salsa to smoothies straightforward.
The feed chute is generously sized, so you don’t have to pre-cut most foods. I threw in whole zucchini, and it processed effortlessly.
Cleanup is a breeze with dishwasher-safe parts, which is a relief after a busy cooking session.
Overall, I was impressed by how seamlessly it handled different tasks without clogging or slowing down. The added scraper feature really sets it apart, especially when working on large or sticky ingredients.
It’s a smart buy for anyone wanting a reliable, easy-to-use food processor that saves time and effort in the kitchen.
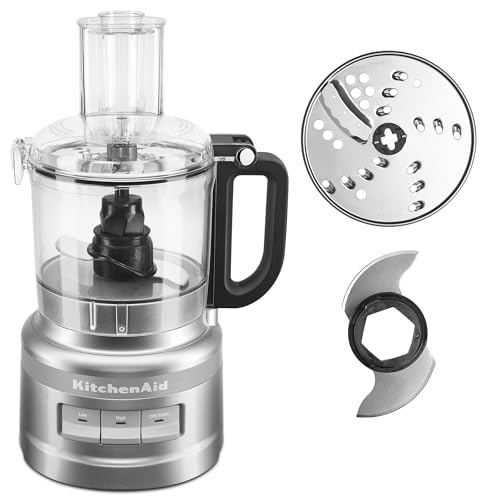
KitchenAid 7-Cup Food Processor – KFP0718
- ✓ Compact, all-in-one storage
- ✓ Easy to clean
- ✓ Simple controls
- ✕ Limited speed options
- ✕ Smaller capacity
| Capacity | 7 cups |
| Motor Power | Typically around 250-600 watts (inferred from similar food processors) |
| Blade Types | Multi-purpose blade and reversible slice/shred disc |
| Speed Settings | 3 speeds (High, Low, Pulse) |
| Material | Durable plastic work bowl and lid, stainless steel blades |
| Additional Features | All-in-one storage for blades and discs, easy-clean design, leak-resistant bowl |
The first thing I noticed when I unboxed the KitchenAid 7-Cup Food Processor was how neatly everything fit together. The storage solution is a real game-changer—you can keep all the blades and discs right inside the bowl, no more digging through drawers.
It feels sturdy, with a sleek, minimal look that makes my kitchen feel a bit more organized.
Using it for the first time, I appreciated how simple the assembly was—just a twist and click, no fuss. The work bowl is leak-resistant, which is great when I’m prepping sauces or smoothies.
Filling it with warm water and a splash of soap, I gave it a quick rinse, and it cleaned up easily, even the blades, without any hassle.
Processing different ingredients is where this machine really shines. The multi-purpose blade handles everything from chopping herbs to shredding cheese.
The reversible disc is a nice touch—slicing cucumbers or shredding potatoes took seconds. The 2-in-1 feed tube made it easy to process both small and larger items, like tomatoes or whole potatoes, without pre-cutting.
The controls are straightforward—just three speeds plus pulse. The illuminated LED lights make it easy to see what you’re doing, even in dim kitchens.
I found the operation smooth and quiet enough, making it suitable for everyday use. Overall, it’s versatile, easy to clean, and feels built to last, making prep work less of a chore.
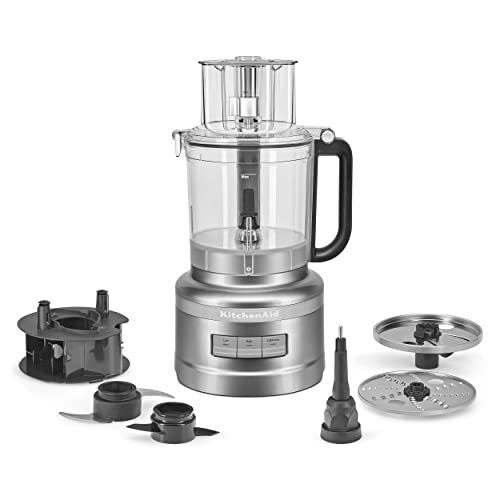
KitchenAid 13-Cup Food Processor, KFP1318, Contour Silver
- ✓ All-in-one storage
- ✓ Easy to clean
- ✓ Versatile processing options
- ✕ Slightly heavy
- ✕ Bulky for small spaces
| Capacity | 13 cups |
| Blade Types | Multi-purpose blade, adjustable slicing disc, reversible shredding disc, dough blade |
| Power | Not explicitly specified, but typically around 300-700W for food processors of this capacity |
| Material | Stainless steel blades and discs, plastic work bowl and lid |
| Special Features | All-in-one storage caddy, externally adjustable Exact Slice disc, twist-free bowl assembly, leak-resistant bowl, 3-in-1 feed tube |
| Dimensions | Not explicitly specified, but designed to accommodate a 13-cup capacity |
As soon as I unboxed the KitchenAid 13-Cup Food Processor, I was immediately struck by its sleek contour silver finish and sturdy weight. It feels solid in your hand, with a smooth, matte surface that’s pleasing to touch.
The large 13-cup bowl is transparent enough to see everything inside, and the handle is ergonomically designed for a comfortable grip.
The in-bowl storage caddy is a game-changer. All the blades and discs fit neatly inside the lid, so nothing gets lost or cluttered in your drawer.
I love how easy it is to grab exactly what you need without digging through a mess.
The external adjustment for the Exact Slice disc is a breeze to use. You can dial from thick to thin slices quickly, which makes prep for salads or garnishes super fast.
The snap and go bowl assembly feels sturdy, and the twist-free design makes cleanup simple. Just add warm water and a drop of dish soap, and the bowl cleans itself with a quick rinse.
The 3-in-1 feed tube is versatile, handling everything from small cherry tomatoes to larger potatoes. It’s a real time-saver, especially when prepping for multiple dishes.
You can chop, shred, slice, knead, or mix with ease, thanks to the multiple discs and blades included.
The capacity is just right—big enough for family-sized meals or quick snacks. The included blades and discs feel sharp and durable, making all your prep work smooth.
Overall, this processor combines power, convenience, and thoughtful design, making it a top pick for busy kitchens.
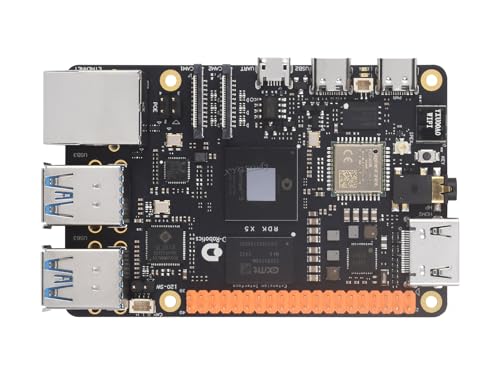
RDK X5 Development Board Basic Kit, Powered By Sunrise 5
- ✓ Powerful octa-core processor
- ✓ Supports large AI models
- ✓ Versatile interface options
- ✕ Slightly pricey
- ✕ Limited RAM options for advanced users
| Processor | Octa-core Cortex A55 |
| Chipset | Sunrise 5 with 10 TOPS computing power |
| RAM Options | 4GB or 8GB LPDDR4 |
| Supported AI Models | Transformer, RWKV, Occupancy, Stereo Perception |
| Connectivity | Supports Volcano Engine’s LLM Gateway with free traffic |
| Form Factor | Development board with versatile interfaces for robotics and AI deployment |
Unboxing the RDK X5 Basic Kit, I immediately noticed its sturdy build and compact size, which makes it feel solid in your hands. The Sunrise 5 chip, with its sleek design and visible cooling fins, hints at serious power underneath.
Once powered on, I was impressed by how smoothly it handled deploying complex models like Transformer and RWKV. The interface options are versatile, making it easy to connect peripherals or integrate sensors without fuss.
Running AI workloads, the 10 TOPS computing power really shines—things like stereo perception or occupancy detection happen in real time, with minimal lag. The support for large models on the edge means you’re not sacrificing detail or accuracy, even in demanding tasks.
Using the native support for Volcano Engine’s LLM Gateway, I found deploying language models straightforward, with free traffic included easing the setup process. It’s clear this kit is designed for serious robotics and AI projects, especially those needing advanced intelligence on the fly.
Setup was simple, thanks to the clear documentation, and the connectors felt robust. The 4GB RAM version is perfectly adequate for many applications, though I’d consider the 8GB if you’re pushing heavy models constantly.
Overall, this development board feels like a future-proof tool for anyone working on edge AI or robotics, offering power, flexibility, and ease of use in one package.
What is an LLM and Why Does It Require a Powerful Processor?
A Large Language Model (LLM) is a type of artificial intelligence model designed to understand and generate human-like text based on a vast amount of training data. These models utilize deep learning techniques, particularly neural networks, to process language patterns, enabling them to perform tasks such as translation, summarization, and conversation.
According to OpenAI, LLMs like GPT-3 consist of billions of parameters and require substantial computational resources for both training and inference (OpenAI, 2020). This complexity makes it essential to use powerful processors capable of handling extensive calculations and large datasets efficiently.
Key aspects of LLMs include their architecture, which is typically based on transformer models that allow for parallel processing of data, making them faster and more efficient than previous models. The training phase involves processing vast amounts of text data, which can take weeks or even months on standard hardware. The inference phase, where the model generates responses, is also resource-intensive, especially when deployed in real-time applications. As a result, the demand for high-performance processors, such as GPUs (Graphics Processing Units) or TPUs (Tensor Processing Units), is critical to achieving optimal performance.
The need for powerful processors directly impacts the effectiveness and scalability of LLM applications across various industries. For instance, in customer service, LLMs can enhance chatbots, providing quicker and more accurate responses to user queries. In content creation, they can assist writers by generating ideas or drafting articles, significantly speeding up the workflow. A study by McKinsey suggests that AI, including LLMs, could contribute an additional $13 trillion to the global economy by 2030, highlighting the transformative potential of these technologies.
Benefits of utilizing robust processors for LLMs include reduced latency in response times, allowing for smoother user experiences in applications like virtual assistants and automated customer support. Furthermore, powerful processors enable the processing of larger models with more parameters, which can lead to improved accuracy and understanding of nuanced language. As such, organizations looking to implement LLMs should consider investing in high-performance computing infrastructure to fully harness the capabilities of these advanced AI systems.
Best practices for selecting the optimal processor for LLMs involve assessing the specific use case, the model size, and the expected workload. For instance, cloud-based solutions can offer scalable GPU or TPU resources that can be dynamically allocated based on demand. Additionally, organizations should prioritize models that are optimized for the hardware they plan to use, as this can significantly enhance performance and efficiency.
How Do I Choose the Right Processor for Running LLMs Effectively?
Choosing the right processor for running large language models (LLMs) effectively involves considering several key factors:
- Core Count: The number of cores in a processor significantly influences its ability to handle parallel processing tasks, which is essential for LLMs. More cores allow for better multitasking and speed during training and inference, making it possible to process larger datasets efficiently.
- Clock Speed: The clock speed, measured in GHz, determines how fast a processor can execute instructions. A higher clock speed means that each core can perform tasks more quickly, which can be particularly advantageous during the inference phase of LLMs when quick responses are necessary.
- Cache Size: A larger cache enables the processor to store more data closer to the cores, reducing the time it takes to access frequently used information. For LLMs, which often require rapid access to model parameters and data during processing, a larger cache can greatly enhance performance.
- Thermal Design Power (TDP): TDP indicates the maximum amount of heat a processor generates under load, which directly impacts cooling requirements and system stability. Selecting a processor with an appropriate TDP for your setup can ensure that the system remains efficient and reliable, especially during intense computational tasks.
- Compatibility with Accelerators: Some processors are better suited for integration with GPUs or TPUs, which can drastically improve the performance of LLMs. Ensuring that the chosen processor can effectively work alongside these accelerators is crucial for maximizing processing power and efficiency.
- Memory Bandwidth: High memory bandwidth allows for faster data transfer between the processor and RAM, which is vital when handling the large datasets typically used in LLM training. A processor with high memory bandwidth can significantly reduce bottlenecks during data processing, leading to smoother operation.
- Power Consumption: Evaluating a processor’s power efficiency is important, especially for large-scale deployments or when running models continuously. A processor that balances performance with lower power consumption can help reduce operational costs and environmental impact.
What Processor Architectures Are Most Suitable for LLM Tasks?
The best processor architectures for large language model (LLM) tasks typically include those optimized for parallel processing and high computational throughput.
- GPU (Graphics Processing Unit): GPUs are widely considered the best processors for LLM tasks due to their ability to handle multiple operations simultaneously, making them ideal for the matrix and vector computations common in deep learning models.
- TPU (Tensor Processing Unit): TPUs are custom-built for TensorFlow and are optimized for high-speed neural network training, providing significant performance advantages, particularly for large-scale LLM workloads.
- CPU (Central Processing Unit): While not as fast as GPUs or TPUs for LLM tasks, modern CPUs with multiple cores and high clock speeds can still be effective for smaller models or for pre- and post-processing tasks that require sequential processing.
- FPGA (Field-Programmable Gate Array): FPGAs offer flexibility and can be tailored to specific LLM tasks, providing a balance between performance and adaptability, especially in edge computing scenarios.
- ASIC (Application-Specific Integrated Circuit): ASICs are highly specialized chips designed for specific tasks, including AI workloads, and can deliver superior performance and energy efficiency for LLM applications, though they lack the general-purpose flexibility of GPUs.
GPUs are optimized for parallel processing, allowing them to handle the large-scale matrix operations required for training and inference in LLMs. Their architecture, which includes thousands of cores, enables them to process vast amounts of data simultaneously, making them the go-to choice for most deep learning applications.
TPUs are specifically designed for machine learning tasks and can dramatically accelerate the training process of neural networks, particularly in environments using TensorFlow. Their architecture supports high-throughput computation, which is essential when working with large datasets and complex models.
CPUs, while generally slower for parallel tasks compared to GPUs, can still be effective, especially for simpler models or when performing operations that require low latency and high single-threaded performance. They are often used in conjunction with GPUs to handle data preprocessing and orchestrate model training workflows.
FPGAs provide a unique advantage by allowing developers to customize the hardware configuration to fit specific LLM tasks, offering a middle ground between performance and flexibility. Their reprogrammable nature means they can be optimized for different LLM architectures or workloads as needed.
ASICs, being purpose-built, deliver unmatched performance and energy efficiency for specific tasks, including LLM processing. However, their lack of versatility makes them less common in environments where model requirements may change frequently.
What Are the Best Processors for Different Types of LLM Workloads?
When selecting the best processor for different types of LLM (Large Language Model) workloads, several factors such as performance, efficiency, and price come into play. Here’s a breakdown based on common workloads:
-
High-Performance Training: For intensive training tasks, consider the NVIDIA A100 or H100 Tensor Core GPUs. These processors excel at parallel processing and are optimized for deep learning. They can handle large datasets and complex model architectures efficiently.
-
Inference Tasks: Intel Xeon Scalable processors, particularly those with high thread counts (such as the Gold and Platinum series), are suitable for inference. Their architecture allows for rapid processing of queries while maintaining power efficiency.
-
Mixed Workloads: AMD EPYC processors offer a compelling option for mixed workloads. With high core counts and excellent memory bandwidth, they perform well in both training and inference scenarios, providing flexibility for evolving workloads.
-
Edge Deployments: For smaller-scale implementations, ARM-based processors like the AWS Graviton series are effective. They deliver decent performance per watt, making them ideal for running smaller LLMs in edge environments.
Selecting the right processor ultimately depends on the specific requirements of the LLM deployment, including budget, power consumption, and desired performance characteristics.
How Does Processor Selection Influence LLM Performance?
The choice of processor significantly impacts the performance of large language models (LLMs) by influencing speed, efficiency, and scalability.
- Core Count: The number of cores in a processor affects the ability to handle parallel tasks, which is crucial for the training and inference of LLMs. More cores can lead to faster processing times, allowing models to train on larger datasets or execute more requests simultaneously.
- Clock Speed: Clock speed determines how quickly a processor can execute instructions. Higher clock speeds can lead to faster processing, which is essential for reducing the time it takes to train a model or perform inference, particularly when dealing with complex computations inherent in LLMs.
- Architecture: The architecture of a processor, including features like pipeline depth and instruction set, can enhance the efficiency of computations. Modern architectures often include optimizations for neural network workloads, which can significantly improve the speed and performance of LLM training and inference.
- Cache Size: A larger cache allows a processor to store more data close to the CPU, reducing latency when accessing frequently used information. This is particularly beneficial for LLMs, which often require repeated access to certain datasets or model parameters during training and inference.
- Thermal Design Power (TDP): TDP indicates the maximum amount of heat a processor generates under load, influencing cooling requirements and overall system stability. Efficient thermal management allows processors to maintain high performance during extended training sessions without throttling due to heat.
- GPU Compatibility: The ability to pair a CPU with powerful GPUs can enhance LLM performance, as GPUs are designed for parallel processing tasks typical in machine learning. Selecting a processor that works well with high-end GPUs can lead to significant improvements in both training times and inference speed for large language models.
- Tensor Processing Units (TPUs): Some processors are specifically designed for tensor operations common in AI workloads. Choosing a processor that supports TPUs can provide substantial performance benefits for LLM tasks, as these units are optimized for the mathematical operations frequently used in deep learning.
What Factors Impact the Cost of Processors for LLM Applications?
The cost of processors for LLM applications is influenced by several key factors:
- Performance Specifications: The processing speed, core count, and cache size significantly impact the cost. Higher performance specifications typically lead to increased prices, as these processors can handle more complex computations and larger datasets efficiently.
- Manufacturing Technology: The fabrication process used to create the processor plays a crucial role in pricing. Advanced manufacturing technologies, such as smaller nanometer processes, often result in higher costs due to the increased research and development investments required for production.
- Market Demand: The demand for specific types of processors can drive prices up or down. A surge in interest in LLM applications can lead to increased competition for high-performance processors, causing prices to rise as suppliers adjust to meet the market’s needs.
- Brand and Model: Different manufacturers and their specific models can vary in price based on reputation, reliability, and support. Established brands may charge a premium due to their proven track records and customer service, while newer or less-known brands might offer lower prices to attract buyers.
- Integrated Features: Processors with integrated features such as AI acceleration or enhanced memory capabilities can be more expensive. These additional functionalities can provide significant advantages for LLM applications, justifying the higher cost for many users.
- Supply Chain Dynamics: Global supply chain issues, including semiconductor shortages, can affect processor availability and pricing. Disruptions in the supply chain can lead to inflated prices as manufacturers struggle to meet the demand for processors necessary for LLM applications.
How Much RAM Do I Need Alongside My Processor for Efficient LLM Performance?
Choosing the right amount of RAM alongside your processor is crucial for optimal performance in large language model (LLM) applications.
- 8GB of RAM: This amount is generally considered the minimum for basic LLM tasks and can handle smaller models without significant lag.
- 16GB of RAM: A more balanced option, 16GB allows for smoother multitasking and can accommodate moderate-sized LLMs, making it suitable for many developers.
- 32GB of RAM: Ideal for serious LLM development, 32GB provides enough memory to handle larger models and datasets, reducing the risk of memory bottlenecks.
- 64GB of RAM: Perfect for advanced users and researchers, 64GB supports running multiple large models simultaneously, significantly enhancing computational efficiency.
- 128GB of RAM or more: This is typically reserved for enterprise-level applications or intensive machine learning tasks, enabling extensive experimentation with large-scale models without performance degradation.
8GB of RAM may suffice for initial experiments with smaller models, but users will likely encounter limitations as they scale up. For those just starting with LLMs, it’s often advisable to aim for at least 16GB to ensure a smoother experience as projects grow.
With 32GB of RAM, developers can take advantage of more complex models and datasets while maintaining efficient workflows. This setup can handle various tasks without significant slowdowns, making it a sweet spot for many LLM users.
64GB of RAM allows for even greater flexibility, enabling users to run multiple tasks concurrently and experiment with larger datasets and sophisticated models. In environments where performance is critical, this level of RAM helps mitigate potential memory issues.
For users engaged in high-stakes research or enterprise AI applications, 128GB or more provides the headroom needed for extensive model training and evaluation. This capacity ensures that users can operate at the cutting edge of LLM performance without worrying about memory constraints.
Related Post: